The Codebase Decides How Small a Change Can Be
If adding a feature means editing five shared files, no amount of discipline makes that change small, and when dozens of agents are merging into the same codebase, every file that each change edits at the same spot is a place for them to collide. That has me rethinking what clean code looks like when the readers and writers are agents. The rules I learned assumed one person reading one file at a time. Clean code for many agents means a system that is safe to change by many hands in parallel.
Clean code had one reader in mind
Good names, short functions, a class that does one thing. Every rule in the clean code canon is aimed at a person sitting down with a file and trying to understand it before they change it. That reader still exists, and I still care about them. I wrote in Code Quality Still Matters that bad code rots the same way whether a model or a person wrote it.
The difference is the number of writers. A team of eight engineers might have a dozen branches open in a week. A team of eight engineers each running a handful of agents can have a hundred open in a day. Readability is a property of one file. Whether a hundred changes can land on the same afternoon is a property of the whole codebase, and the old rules don’t say much about it.
Shared files are where agents collide
Every codebase has a few files that everything touches. The routes file. The dependency injection container. A constants module that grew to 900 lines. An enum of every event type, a feature flag registry, a CHANGELOG that every PR appends to.
Human teams already know the cost. Two people add a route on the same day, the first one merges, and the second one hits a conflict on the same lines. Their feature is done, and now they’re blocked on untangling someone else’s change from their own before it can ship. With a handful of engineers, that happens often enough to be annoying. Ten agents each appending one line to the same registry is worse. Each one that conflicts has to rebase, rerun its checks, and try again, and every merge that lands in the meantime starts the cycle over for the rest: nine conflicts after the first merge, eight after the next, up to 45 rebases and CI reruns before the last change lands. Sooner or later, one of them will resolve the conflict by dropping a line that wasn’t its own.
Git merges edits to different parts of a file cleanly. Conflicts come from edits to adjacent lines, such as appends at the end of a file or insertions next to each other in a sorted list. That makes me think a file every change appends to at the same spot should count as a smell, even when the file itself reads fine. For an append-only file like CHANGELOG, one line in .gitattributes with merge=union tells Git to keep both sides. The broader way out is to let each module register itself where it lives: routes declared next to the handler, events defined by the module that emits them, changelog entries as one file per change that a script collects at release time. The code would end up slightly more spread out, and two features would no longer edit the same file.
Text conflicts are the failure you can see. The worse one merges cleanly. Agent A renames a function while agent B adds a new caller of the old name. Each change passes its own checks, Git sees no overlapping lines, and the combined result is broken. Git can’t flag this. Only the type checker and tests running on the combined result catch it, which means a merge queue.
Boundaries and contracts do the coordinating
An agent working inside one module shouldn’t need to know how the module next door works. It needs to know what that module promises. That promise has to be written down somewhere a machine can check it: a type signature, a schema, a published interface with tests against it.
Implicit contracts were always a risk, and I made the case for explicit over implicit long before agents showed up. With people, the risk was softened by memory. The engineer who wrote the billing module remembered that amount was in cents. An agent remembers nothing between sessions. If the contract only lives in someone’s head, the agent will guess, and the guess will look reasonable right up until production.
Strong boundaries also shrink what an agent has to load before it can start. A module with a small interface and no reaching into its neighbors’ internals is one an agent can change while holding only that module in context. That’s the same reason the harness around the agent matters: the type checker enforces the contract on every edit, so a boundary violation fails in seconds instead of in review. Explicit contracts are also what turn a semantic conflict like that rename into a build failure in the merge queue instead of a bug in production.
Small enough to merge without a conversation
The last property is size. A change that touches one module, adds one capability, and passes its own checks can merge without anyone negotiating. A change that touches six modules needs someone to sequence it against the other work in flight, and that someone is usually a person.
Small diffs were already one of the guardrails I listed in Humans Out of the Loop, because a one-line change has one thing that can go wrong. Small changes have always had a second benefit too. The fewer files a change touches, the lower the odds that someone else is in those files at the same time, and people arguing for small commits and small functions made that case long before agents wrote any code. It was usually the side benefit, mentioned after readability and easier review. With dozens of agents merging in parallel, it moves to the front of the list.
The codebase decides how small a change is allowed to be.
Open questions
I don’t have this figured out. A few questions I keep coming back to:
- How far to split shared files before the codebase gets harder for a human to navigate. Ninety files of one route each is its own kind of mess.
- Whether merge conflict rate is a useful health metric. I suspect it is, and I suspect most teams don’t track it.
- How much of the clean code canon still pays for itself. Early evidence says most of it does. In 660 Claude Code trials on clean and messy versions of the same repos, Trivedi and Schmitt found no change in pass rate, but the cleaner side used 7.1% fewer input tokens and revisited 34% fewer files. Borg et al. found that files with a Code Health score of 9 or higher broke less often when open models refactored them, though the gap wasn’t significant for Claude Code. Short functions help an agent too. Some of the indirection we added to make code easy to extend may now cost more in context than it saves. In the same Claude Code trials, a cleanup that extracted helpers around the core logic but left that logic in place raised agent input tokens by 8%.
Here is my summary of where the two lists overlap. It draws on the canon, the two studies above, and this post, so read it as my reading of the evidence, not independent support for it.
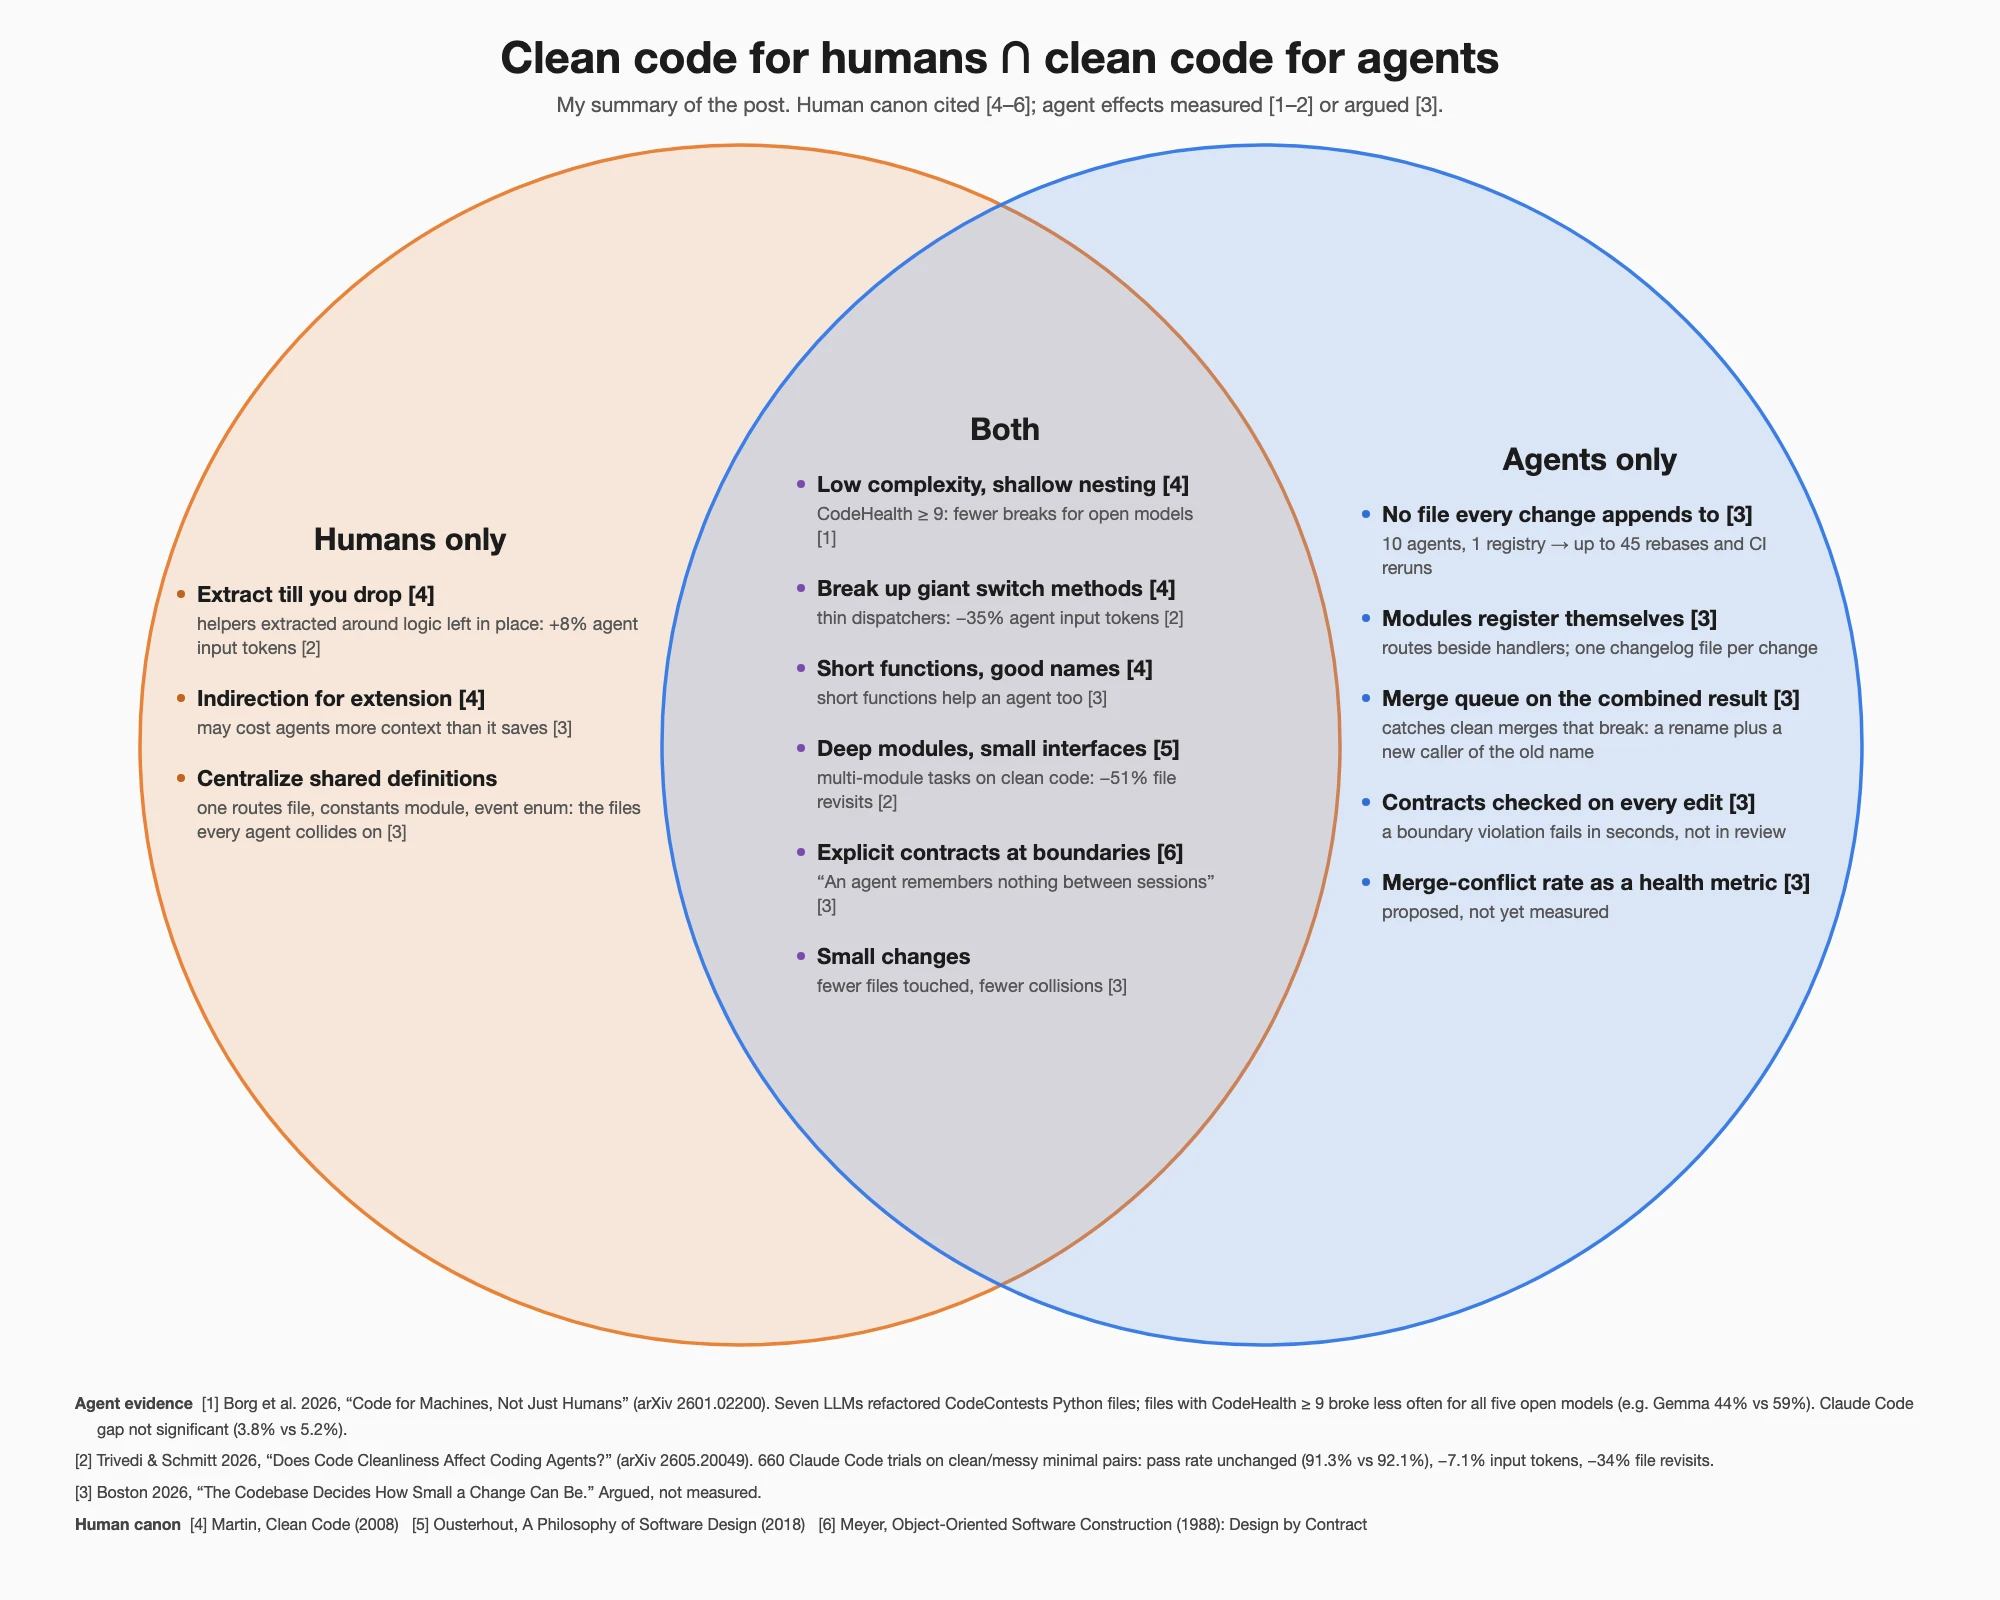
The direction feels right to me. The goal is shifting from code that one person can understand toward a system that many agents can change safely at the same time. Those overlap a lot, but they aren’t the same goal, and the gap between them is what I want to understand better.
As I come across these standards, I write them down in a skill, making-code-agent-friendly. It audits a codebase for the places parallel agents will collide, reviews a diff for the same problems, and refactors a finding once I decide it is worth fixing. The rules in it are my current best answers, so expect it to change.